
In this post
Get the latest insights delivered to your inbox
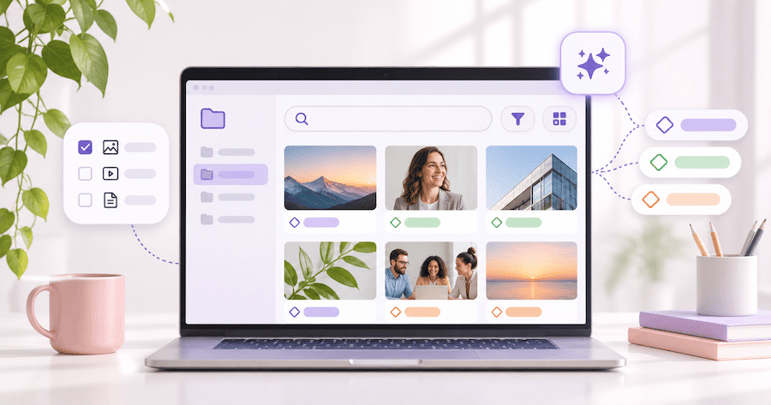
You've invested in a digital asset management (DAM) system to make finding and managing images easier. But now someone has to tag thousands of files before anyone can find them.
Every image needs a description. Every video needs keywords. Someone has to decide which category each file belongs to, and everyone seems to have a different opinion about how things should be organised.
Before long, uploading content feels like more work than finding it.
So, do you really need to tag every image in your DAM?
The short answer is no. Not every image needs extensive manual tagging. But every asset does need enough useful information to make it findable, manageable and safe to use.
The challenge is knowing what information matters, what can be automated and what you can safely leave out.
Why Do We Tag Images in a DAM?
Tagging is one way of adding metadata to digital assets.
Metadata is information that describes a file, helping people and systems understand what it contains, where it belongs and how it can be used.
For example, an image might have metadata describing:
- Content: A group of employees attending a company event
- Location: Brisbane, Australia
- Department: Human Resources
- Campaign: Employee Engagement 2026
- Usage rights: Internal communications only
- Approval status: Approved for use
- Expiry date: December 2027
Some of this information describes what's visible in the image. Other information explains the business context or rules governing its use.
That distinction matters.
Modern DAM platforms can increasingly recognise objects, scenes and text within images. But they don't necessarily know why your organisation created an asset, which campaign it belongs to or whether the people pictured have consented to its use.
Good metadata helps answer both questions:
- Can I find the asset I need?
- Can I use it for what I'm planning to do?
If your team regularly struggles with the first question, read our related article, Why Can't Anyone Find Anything in Your DAM?.
The Problem With Tagging Everything
It's easy to assume that more metadata means better search results.
But that's not necessarily true.
Imagine your marketing team uploads 500 photographs from a company event. Your DAM requires users to complete 15 metadata fields for every image.
That's 7,500 individual field entries if every field must be completed separately.
Even if each entry takes just five seconds, that's more than ten hours of administrative work.
And that's before anyone starts reviewing the tags for accuracy.
Now imagine doing that every week.
When tagging becomes too demanding, several things can happen.
1. People start skipping the DAM
If uploading files requires too much effort, employees may keep working in SharePoint, Google Drive or local folders instead.
The DAM becomes an extra step rather than the easiest place to manage content.
2. Metadata becomes inconsistent
One person tags an image "staff", another uses "employees" and someone else chooses "team".
All three descriptions may be correct, but inconsistent terminology can make searching and filtering less reliable.
3. Users enter information just to complete required fields
When people don't understand why a field matters, they may select whatever option allows them to finish uploading.
You end up with a library full of metadata, but much of it isn't particularly useful.
4. Important information gets lost among unnecessary details
An image might have 20 descriptive keywords but still be missing its approval status or usage restrictions.
The system knows what's in the picture, but not whether anyone is allowed to publish it.
The goal isn't to collect as much metadata as possible. It's to collect the right metadata, consistently.
What Metadata Does Your DAM Actually Need?
A useful starting point is to separate metadata into three categories.
1. Essential metadata: What you need to manage the asset
This information supports governance, permissions and appropriate use.
Depending on your organisation, essential metadata might include:
- Asset owner or responsible department
- Approval or publication status
- Copyright and licensing information
- Consent requirements
- Usage restrictions
- Expiry or review date
Not every field needs to be mandatory for every asset.
For example, a product photograph may require licensing and product information, while an image featuring identifiable people may require consent-related information.
The key is to define what's essential for different types of content.
2. Search metadata: What helps people find the asset
This is the information people are likely to use when searching.
Examples include:
- Product name
- Campaign or project
- Location
- Event name
- Subject or topic
- Department
- Content category
Rather than guessing which keywords might be useful, consider how people actually search.
Does your sales team search by product? Does your communications team search by event? Do regional offices need to filter content by location?
Your metadata structure should reflect these real-world requirements.
3. Descriptive metadata: What can potentially be automated
Descriptive metadata identifies what's visible or detectable in a file.
For example:
- People
- Buildings
- Vehicles
- Landscapes
- Colours
- Objects
- Text appearing within an image
Many modern DAM platforms offer AI-powered tools that can help generate this information automatically.
This reduces the need for people to manually describe every image.
However, automatically generated descriptions should be treated as assistance, not unquestionable facts.
AI can misidentify objects, miss important context or generate tags that aren't useful to your organisation.
Is your DAM creating more work than it saves?
Can AI Tag Images Automatically?
Yes. AI-powered tagging can significantly reduce manual metadata work, particularly when organisations manage large volumes of photographs and videos.
Depending on the platform, AI capabilities may include:
Object recognition: Identifying items such as vehicles, buildings, furniture or equipment.
Scene recognition: Recognising settings such as offices, beaches, construction sites or outdoor events.
Optical character recognition (OCR): Extracting text visible in images or documents.
Speech transcription: Converting spoken content in videos into searchable text.
Natural language search: Helping users find content using everyday descriptions rather than exact keywords.
For example, instead of manually tagging every image with "woman", "laptop", "office" and "meeting", a user might search for:
Find photos of people collaborating around a laptop in an office.
Where supported, AI-powered search may be able to identify relevant images without requiring those exact words to be entered manually.
That's a major improvement over traditional keyword-only searching.
But AI doesn't know everything about your business
Consider a photograph of a group of people standing outside a community centre.
AI might identify:
- People
- Building
- Outdoor setting
- Group photograph
But it may not know:
- The name of the community programme
- Which organisation owns the photograph
- Whether everyone has provided consent
- Whether the image can be used in fundraising campaigns
- Whether the photograph is approved for publication
Those details come from your organisation's processes and knowledge.
AI can help describe an asset. Your organisation still needs to define what the asset means and how it can be used.
This is particularly important for government agencies, education providers, not-for-profits and organisations managing consent-sensitive images.
For more on managing permissions and consent, explore our DAM governance and metadata resources.
Five Ways to Reduce Manual Image Tagging
If your team is spending too much time entering metadata, the solution may not be to remove tagging altogether.
Instead, look at how your metadata model and upload processes are designed.
1. Reduce the number of mandatory fields
Review every required metadata field and ask:
What happens if this field is left blank?
If the answer is "not much", it may not need to be mandatory.
Keep required fields focused on information that supports essential business processes, governance and retrieval.
Additional fields can remain optional or apply only to relevant asset types.
2. Use controlled vocabularies
Instead of asking users to type keywords freely, provide predefined options for important fields.
For example, a department field might include:
- Marketing
- Communications
- Human Resources
- Sales
- Operations
This prevents variations such as "HR", "Human Resource" and "People Team" from fragmenting search results.
Controlled vocabularies are particularly useful for business-specific information that AI cannot reliably determine.
3. Apply metadata in bulk
If you're uploading 200 photographs from the same event, you shouldn't need to enter the event name 200 times.
Many DAM platforms allow metadata to be applied to multiple assets simultaneously.
Shared information such as event name, campaign, department or photographer can often be added in a single action.
Individual assets can then receive additional information where necessary.
4. Use automation where it makes sense
Depending on your DAM platform and configuration, metadata may be populated through:
- AI-generated descriptions and tags
- Existing file metadata
- Upload templates
- Folder-based or workflow rules
- Integrations with other business systems
For example, product images coming from a product information management (PIM) system may already have product identifiers and category information.
There's little value in asking someone to enter that information again manually if it can be transferred reliably.
5. Review how people search before changing your taxonomy
Before adding more fields, look at the searches people perform and the assets they struggle to find.
Are they searching by campaign name, subject, location or product?
Are searches failing because metadata is missing, or because users don't know which terms to use?
Sometimes the solution is better metadata. Sometimes it's a simpler taxonomy, improved search configuration or better user guidance.
You don't want to spend months tagging thousands of files only to discover that the real problem was how the DAM was configured.
A Practical Example: Managing 10,000 Images
Imagine an organisation has 10,000 photographs spread across shared drives and is preparing to migrate them into a DAM.
Its first instinct might be to create a comprehensive tagging framework and manually describe every photograph before migration.
But a more practical approach could look like this:
Step 1: Audit the collection
Identify duplicate, outdated and irrelevant images. Determine which assets are worth migrating and which should be archived.
Step 2: Group related content
Organise photographs by event, campaign, project or other meaningful business categories.
Step 3: Define essential metadata
Decide which information must be recorded for governance and appropriate use, including rights, consent and approval requirements.
Step 4: Apply shared metadata in bulk
Use bulk editing or automated workflows to populate information common to groups of assets.
Step 5: Use AI to support descriptive tagging
Where available, generate searchable descriptions and tags automatically, reviewing outputs where accuracy matters.
Step 6: Test the library with real users
Ask employees to find specific images using the terms and filters they would normally use.
If they can't find what they need, investigate why before adding more metadata fields.
This approach focuses effort on making the collection useful rather than simply completing a tagging exercise.
When Is Manual Tagging Still Worth It?
Despite advances in AI, there are situations where manual metadata remains important.
Specialised or technical content
An AI tool might recognise a piece of industrial equipment but not identify its exact model, internal product code or technical application.
Brand and campaign assets
An image might belong to a particular brand campaign, market segment or approved creative collection. These relationships often require business-specific information.
Rights and consent management
AI should not be relied upon to determine whether an organisation has permission to publish an image of an identifiable person.
Regulated or sensitive content
Government, healthcare, education and other organisations may need specific classifications, review processes and access restrictions.
Historical and archival collections
Images may contain people, locations or events that require specialist knowledge to identify accurately.
In these cases, manual metadata isn't wasted effort. It provides information that would otherwise be unavailable or unreliable.
The important distinction is between information that genuinely requires human knowledge and information that can be captured more efficiently.
Your Metadata Model Should Evolve With Your DAM
One of the biggest mistakes organisations make is treating metadata design as a one-off implementation task.
They establish a taxonomy, configure the fields and assume the work is finished.
But business requirements change.
New departments begin using the DAM. New content types are introduced. Campaign structures evolve. AI search capabilities improve.
A metadata model that worked well three years ago may now be creating unnecessary work.
Regular reviews should consider:
- Which metadata fields are people actually using?
- Are required fields slowing down uploads?
- Are users creating inconsistent or duplicate tags?
- Which searches are returning poor results?
- Could automation replace repetitive manual entry?
- Are important governance fields being completed accurately?
These questions can reveal opportunities to simplify your DAM without compromising control.
If your organisation has already invested in DAM but struggles with adoption or searchability, our article Is It Really a DAM Problem? 7 Reasons Your DAM Isn't Working explores other common causes.
The Best DAM Metadata Is the Metadata People Will Actually Use
You don't need to manually tag every image with every possible keyword.
You need a metadata structure that makes it easy for people to find the right content, understand what they're allowed to do with it and manage it throughout its lifecycle.
That means balancing three priorities:
- Findability: Can people locate the content they need?
- Governance: Can they identify which assets are approved and safe to use?
- Usability: Can people upload and manage assets without unnecessary administrative work?
Too little metadata creates confusion. Too much creates friction.
The right balance depends on your organisation, your content and how your teams work.
And finding that balance is often more valuable than adding another hundred tags.
Spending Too Much Time Tagging Your DAM Assets?
If your team struggles with metadata, search or asset organisation, the problem may be how your DAM has been structured rather than the software itself.
At databasics, we help organisations across Australia and New Zealand review their DAM setup, simplify metadata structures and improve the way teams find and manage digital content.
Whether you're implementing a new DAM or improving an existing one, our consultants can help you identify what's working, what's creating unnecessary effort and where improvements will make the biggest difference.
Explore our DAM consulting services
Or talk to a DAM specialist about your specific challenges.
